research · JUL 29, 2026
The limits of agent scaffolding
A scaffold controls what a model sees, which actions it can take, and when it tries again. Its value depends on how those choices change complete-task performance after their costs are counted.
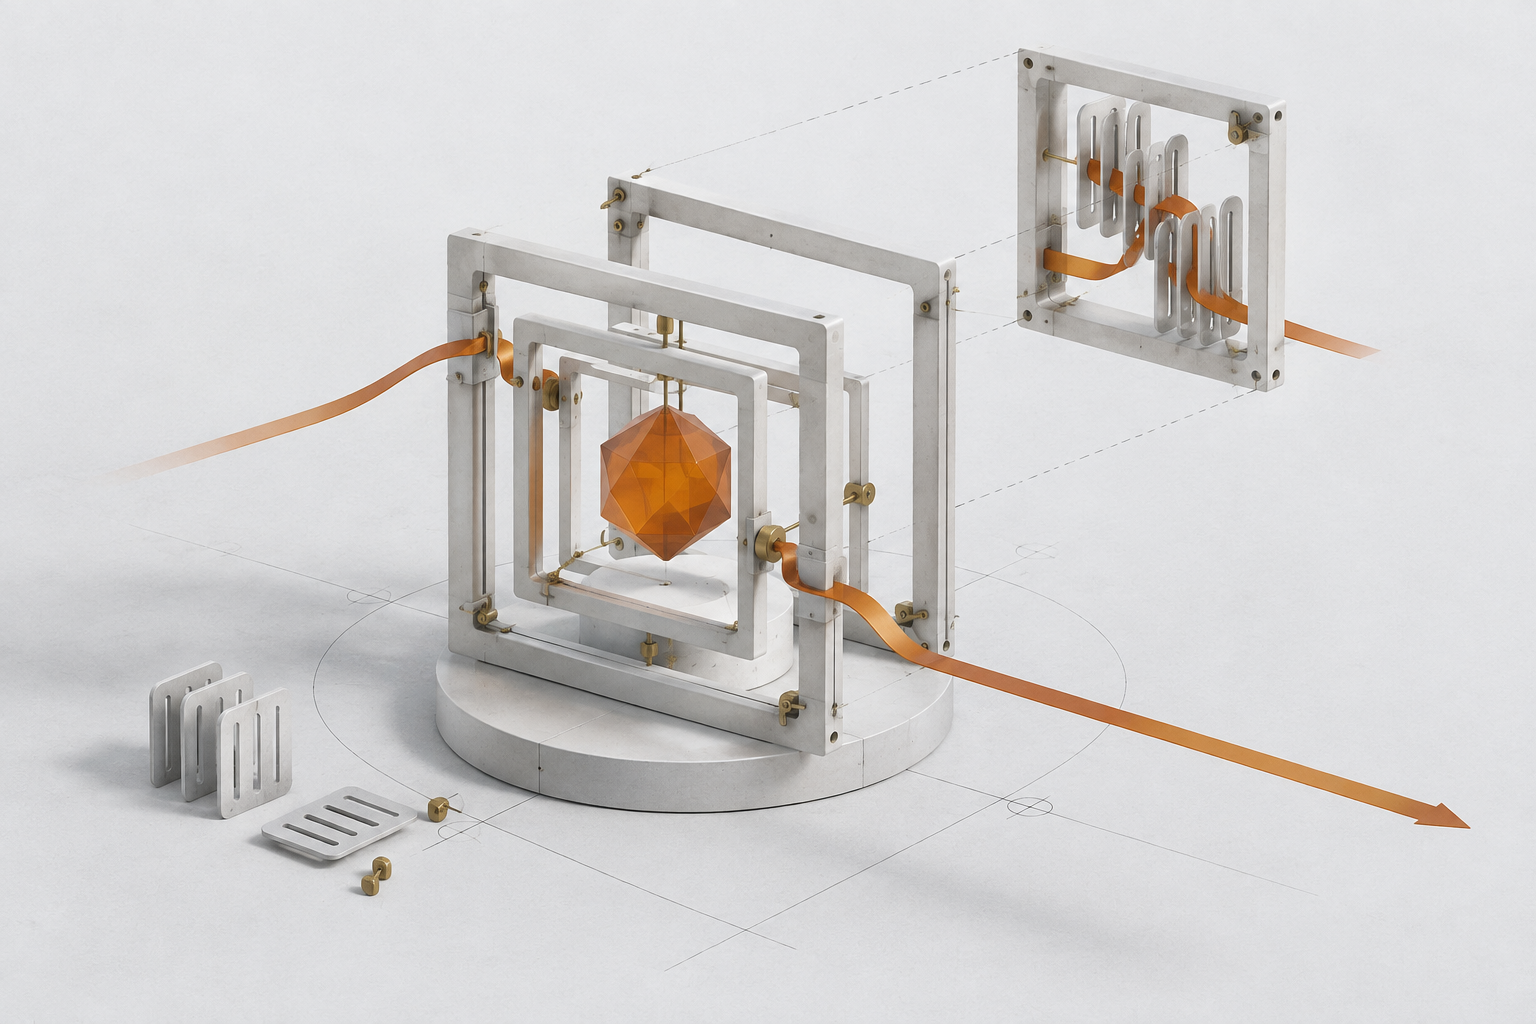
An agent's behavior depends on more than its model. Software selects the context, exposes tools, manages memory, and decides whether to accept an output or request another attempt. This surrounding machinery is the scaffold. It can make a capable model useful, and it can make the same model spend its budget coordinating work it could have completed directly.
The important boundary is between the model's proposed behavior and the behavior the complete system executes. A planner constrains the sequence of decisions. A tool wrapper changes what one action accomplishes. A verifier decides which outputs survive. These mechanisms participate in the effective policy even when the model weights remain fixed.
Our work on Optimus treats that boundary as an experimental variable. The question is which structure helps a particular model complete a particular class of tasks, and which structure adds cost or excludes useful behavior.
The scaffold changes both sides of a decision
Before inference, the scaffold constructs the model's input. Retrieval can recover a missing fact or introduce an obsolete instruction. Summarization can remove repetition or discard the distinction that determines the next action. Scheduling decides which worker receives which part of the problem.
After inference, the scaffold interprets the proposal. It may validate arguments, execute a tool, route the result to another agent, or reject the proposal and request a revision. The model's output is therefore one intermediate event in a larger decision process.
ReAct studies an organization of reasoning and environment interaction; CoALA describes memory, actions, and decision processes in language-agent architectures. These perspectives help explain why changing a wrapper can change capability without changing the underlying model.
The consequence is model-dependent. A procedure that compensates for one model's weak planning may duplicate another model's internal computation. A strict intermediate format can improve execution reliability while making an unfamiliar solution difficult to express. The model and scaffold need to be evaluated together.
Extra stages consume the budget they might improve
Let J_B(M,H) denote expected task utility for model M and scaffold H under a specified total resource budget B. Adding a mechanism produces a new scaffold H′. Its marginal value is:
The added mechanism consumes the same budget. Planning calls, verification, and coordination cannot be treated as free preprocessing. A component can increase the probability of a correct local decision while reducing the number of decisions the system can afford before its deadline.
Latency, compute, and monetary cost are different constraints, so we declare which budget is held fixed and report the others separately. The comparison also needs failure outcomes. Looking only at successful runs hides cases where a mechanism consumed the budget without producing an answer.
Conditional use can improve this tradeoff. A verifier might be useful for an uncertain output and wasteful for a deterministic operation with an executable check. But deciding when to invoke it is another policy, with its own errors and cost. We compare selective use with both always-on and omitted versions.
Retries need a changed condition
Repeated attempts help when they explore alternatives with a meaningful chance of success. They help less when a shared cause dominates: unavailable evidence, a bad task decomposition, or an execution interface that cannot express the needed action.
The familiar independent-trial calculation overstates the benefit when failures are correlated. An agent that repeatedly reconstructs the same mistaken premise may produce different text while taking effectively the same action. A retry budget then buys variation in presentation rather than variation in strategy.
We inspect what changed between attempts. New evidence can justify another decision. A repaired tool can make the same decision executable. A different decomposition can expose a route the original plan excluded. Without a changed condition, the recovery loop needs stronger justification than the fact that the previous attempt failed.
This reasoning also applies to multi-agent systems. Several workers do not supply independent evidence merely because they have separate contexts. Shared instructions, training, and retrieved material can produce correlated mistakes. Voting needs to be evaluated against the sources of disagreement and common failure, including its coordination cost.
A good component can make a worse system
Component metrics can miss the consequences of their outputs. A retrieval system can return relevant passages that obscure a more decisive fact. A critic can identify genuine defects but prevent any result from being delivered. A subtask can pass its checks while leaving an assumption between subtasks unresolved.
These are composition problems. The experiment must include the behavior of the consumer of each output. We examine the resulting trajectory: which decision changed, what new work became necessary, and whether the complete task improved.
State management deserves particular attention. A current execution status and a historical transcript answer different questions. If an agent has to reconstruct control state from narrative, it incurs additional retrieval and interpretation. If a summary hides needed history, it may act on an incomplete account. The interface should preserve the distinctions required by the next decision and provide a way to inspect the supporting evidence.
Some constraints remain requirements regardless of benchmark utility. Permission enforcement and provenance cannot be removed merely because an unconstrained run is faster. Their implementations can be improved, but the comparison must preserve the obligations they serve.
Revisit the architecture when the model changes
A scaffold is a set of assumptions about the model and its operating conditions. Those assumptions can become stale. A stronger model may need fewer mandatory planning stages; a new tool may make an old decomposition inefficient; a different task distribution may make a previously useful memory misleading.
We use this as a reason to revisit architecture through controlled interventions. Hold the model fixed while changing the mechanism, then repeat with another model. Test task families where the mechanism has a plausible purpose as well as those where it may introduce overhead. Account for retries and unfinished work.
Optimus provides a working surface for implementing these alternatives and inspecting their execution. The research objective is a system whose structure follows from demonstrated needs. A scaffold earns its place through the behavior it enables after its own costs, restrictions, and failure modes are included.
Read next
Searching over learning systems
A learner improves within a design. Optimus investigates the design itself: the interfaces, algorithms, data, and feedback that determine what the learner can discover.
research · SEP 12, 2026
Discovering simpler systems through optimization
Optimization can uncover behavior that needs less machinery than the search that found it. The next question is which weights, decisions, and dependencies can disappear without losing the capability.
research · AUG 24, 2026